BINND: Deep Learning Predicts Dissimilar DNA-DNA Binding and Engineers Hyperconnected Networks
Disclaimer: the text on this page was written with the help of AI, based on our published paper.
Published in Nature Communications (2026). Read the paper
Bioengineering has largely been built on orthogonality: the assumption that molecular components should interact with exactly one intended partner, and that weak or non-specific interactions are defects to be designed away. That assumption is convenient, but it is also expensive. It confines designs to a small, well-behaved corner of the possible sequence space, caps how far a system can scale, and offers little help when a synthetic system has to operate inside a natural background of high sequence diversity. Many native systems, from chromatin regulation to cellular signaling, do the opposite: they use messy, multivalent networks in which each component touches several others.
DNA-DNA interactions are a good testbed for this idea. Predicting whether two highly similar strands will bind is straightforward, which is why DNA is often described as programmable. The unsolved part is off-target binding among dissimilar sequences, which is precisely what matters in a genome or a large DNA data storage database. Conventional predictors - Levenshtein and Hamming distance, GC content and melting temperature, and thermodynamic tools such as NUPACK and Primer3 - work well near perfect complementarity and then degrade sharply. Worse, they fail most severely in the region where the bulk of the sequence space actually lives, leaving bound and unbound populations heavily overlapped rather than cleanly separated.
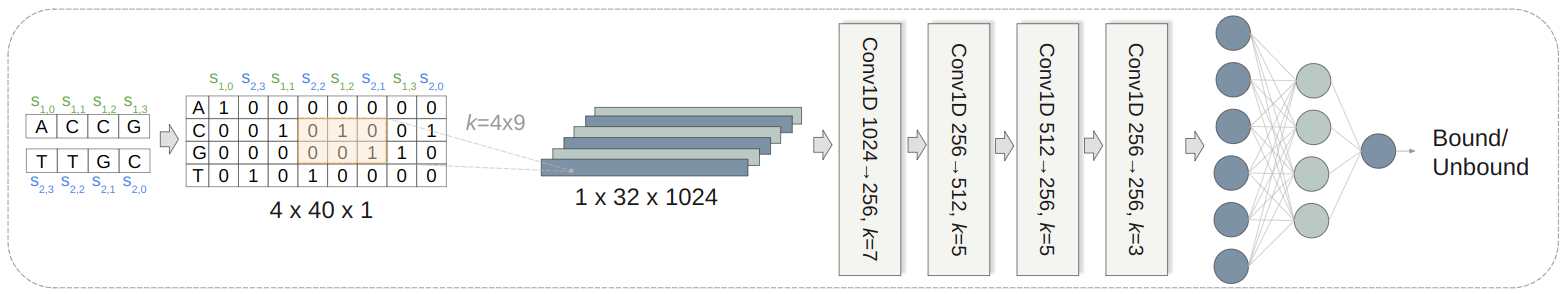
We developed BINND (Binding and Interaction Neural Network for DNA), a convolutional neural network trained on experimental rather than simulated data. The training set came from an ultra-high-throughput pulldown assay run across 26 bait sequences, yielding roughly 144.6 million unique sequence pairs with balanced bound and unbound classes. The data are extremely sparse - about 92% of unique sequences appear exactly once - which shaped how the model had to be labeled and trained. Training and benchmarking were carried out on a high-performance computing cluster.
BINND reaches accuracies above 80% with an AUC of 0.88, generalizes across diverse sequences, and outperforms Levenshtein distance, NUPACK, and Primer3 by at least 10 percentage points in classification accuracy on an identical test set. It is also far cheaper to run, at roughly 54x the speed of NUPACK and 7x that of Primer3. A reduced variant, BINND-Lite, trains 2.2x faster on a GPU and runs inference 10x faster on a CPU for a small accuracy cost. One control is worth highlighting: the same architecture trained on randomly generated sequence pairs instead of experimental ones lands at 50% accuracy, i.e. chance. The model is not recovering complementarity rules in the abstract; it is learning what the wet lab actually measured.
To show that this supports design and not only prediction, we built a searchable DNA network encoding fictitious children's storybook characters. Each of the 26 bait sequences stands for an abstract attribute, and characters are represented by prey sequences that deliberately bind several baits at once. Querying an attribute retrieves every character that has it. The network is hyperconnected on purpose: it works because of the overlapping, non-orthogonal interactions that conventional design rules would have eliminated.
This was joint work with Karishma Matange, with whom I share first authorship, together with Kyle J. Tomek, Kevin Volkel, Doug Townsend, and our advisors Prof. James Tuck and Prof. Albert Keung. I led the computational side: the model, the data pipelines, and the HPC workflows.